Freya Sullivan · 11 September 2026
Examining Buffer Management Innovations in High-Volume Data Environments
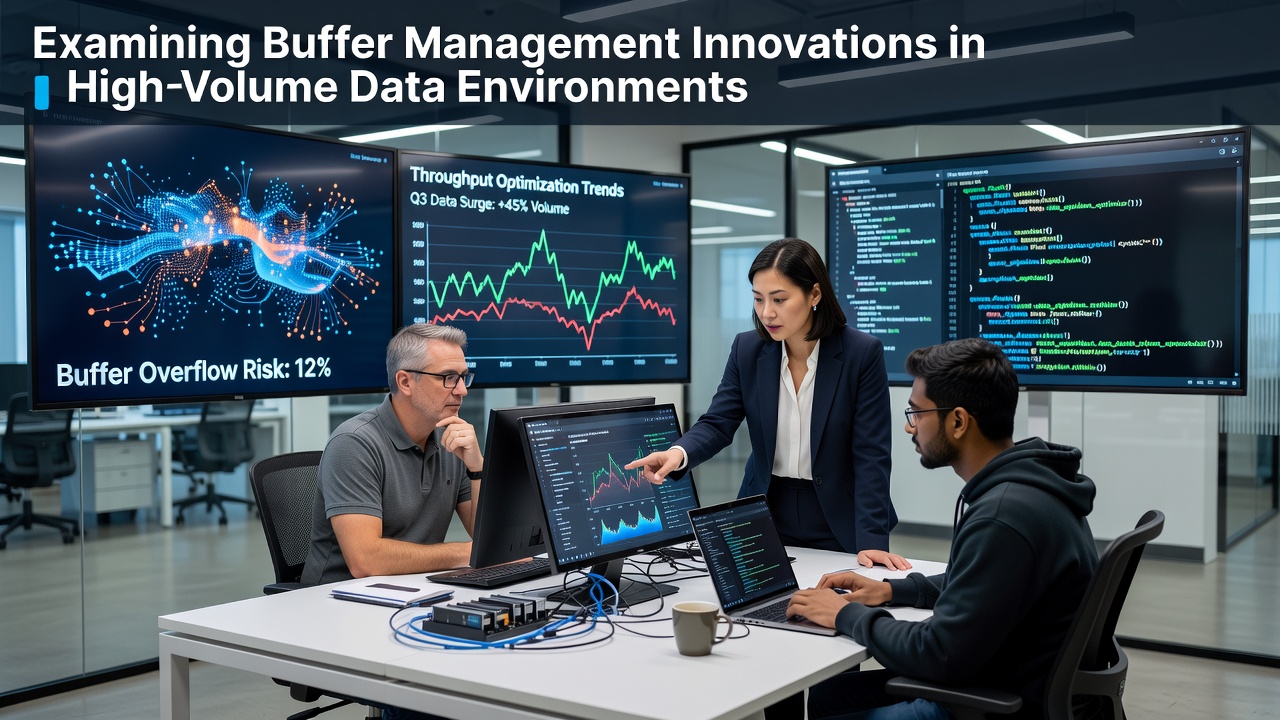
Buffer management plays a central role in systems that handle large volumes of data, where memory allocation between storage devices and processing units determines throughput rates and latency levels. Researchers have documented how traditional fixed-size buffers often fall short in environments that process streaming analytics, financial transactions, or scientific simulations, and this shortfall has driven development of more responsive techniques. Data from industry reports shows that mismatches between buffer capacity and workload patterns create bottlenecks, particularly when input rates spike without warning.
Core Challenges in High-Volume Settings
High-volume data environments generate continuous streams that exceed the capacity of conventional memory hierarchies, and observers note that static buffering schemes struggle to adapt when traffic patterns shift across multiple nodes. Studies conducted in distributed database clusters reveal that underutilized buffers waste resources while overcommitted ones trigger frequent evictions, both of which degrade overall performance metrics. Engineers at research institutions have measured these effects in production workloads, finding that latency variance increases sharply once queue depths surpass predefined thresholds.
Network-attached storage systems compound the issue because round-trip times add another variable that buffer logic must account for, and measurements collected across geographically dispersed facilities confirm that distance-related delays interact directly with buffer sizing decisions. Those who monitor these systems report that peak-hour congestion periods expose the limits of algorithms designed for average-case scenarios rather than tail latencies.
Recent Technical Advances
Adaptive buffering algorithms now incorporate real-time telemetry to resize pools on the fly, and implementations deployed in cloud environments demonstrate measurable reductions in page fault rates. Hardware vendors have introduced specialized controllers that offload buffer management tasks from general-purpose CPUs, allowing software layers to focus on higher-level coordination. In September 2026, several research consortia plan to release updated benchmarks that compare these hardware-assisted approaches against purely software-based methods under standardized high-throughput test suites.
Machine learning models trained on historical access patterns predict future buffer demand with increasing accuracy, and deployments in large-scale analytics platforms show that predictive pre-allocation cuts idle time between processing stages. Researchers at academic computing centers have published results indicating that reinforcement learning variants outperform heuristic rules when workloads contain recurring but irregular bursts. These models require careful feature engineering to avoid overfitting to specific datasets, yet the gains in sustained throughput justify the added complexity for many operators.
Implementation Examples Across Sectors
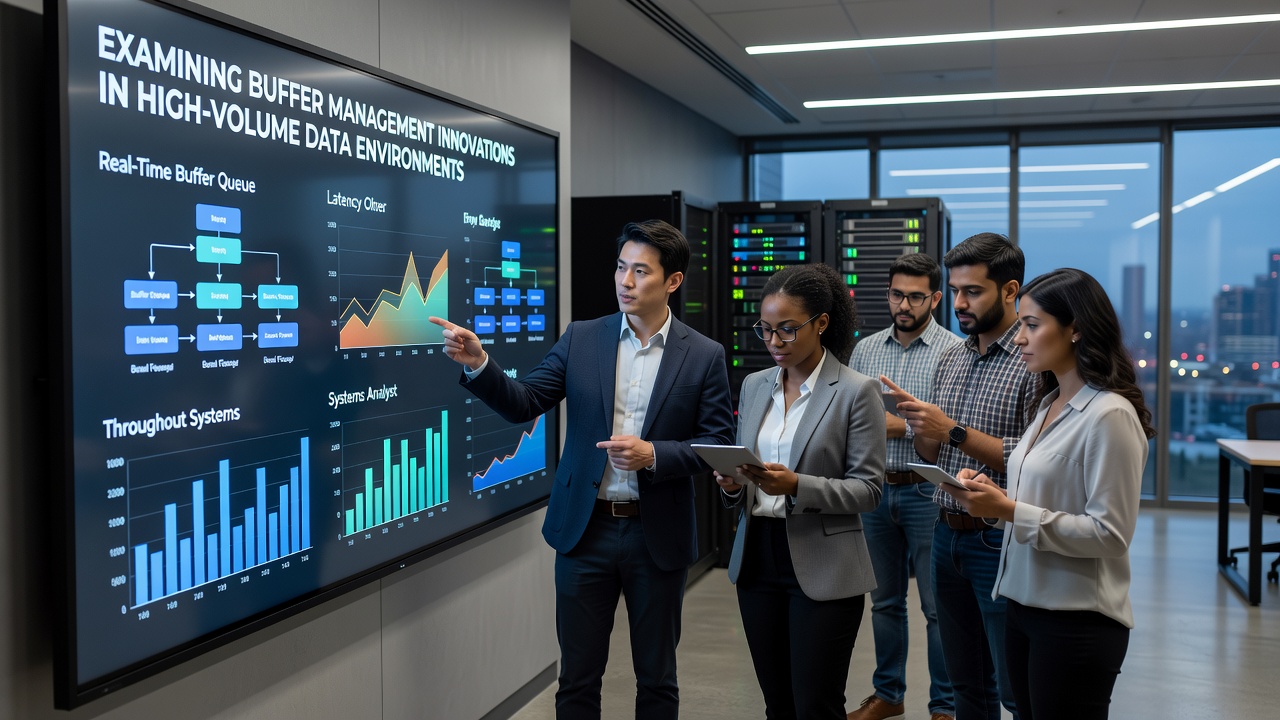
Financial exchanges rely on sub-millisecond response times, and buffer innovations there focus on lock-free data structures that reduce contention during simultaneous order arrivals. Healthcare data platforms handling electronic records apply similar techniques to manage intermittent high-volume uploads from remote monitoring devices, ensuring that query responses remain consistent even when daily ingestion volumes double. Telecommunications providers have integrated buffer management directly into edge computing nodes, where local processing reduces backhaul traffic and improves user experience metrics during video streaming peaks.
One study from the National Institute of Standards and Technology examined buffer behavior in high-performance computing environments and documented how hybrid DRAM-NVM configurations extend effective buffer capacity without proportional increases in power consumption. National Institute of Standards and Technology publications provide detailed traces that illustrate the interaction between buffer replacement policies and application-level access patterns. Observers note that these traces have become reference material for teams designing next-generation storage fabrics.
Integration with Emerging Architectures
Container orchestration platforms now expose buffer metrics through standard APIs, enabling automated scaling decisions that react to memory pressure signals before they affect application performance. This integration allows operators to maintain service-level objectives across thousands of concurrent instances without manual tuning. Data indicates that such automated systems reduce operational overhead while preserving headroom for unexpected traffic surges.
Persistent memory technologies introduce new variables because their access latencies sit between DRAM and flash, and buffer management logic must decide when to stage data in each tier. Experiments conducted on prototype systems show that tier-aware buffering improves both bandwidth utilization and endurance of underlying media. European research initiatives have contributed comparative analyses that highlight regional differences in deployment constraints, particularly around energy efficiency targets.
Conclusion
Buffer management continues to evolve in response to growing data volumes and stricter performance requirements, with innovations spanning algorithmic improvements, hardware acceleration, and cross-layer coordination. Measurements gathered from production deployments confirm that adaptive and predictive approaches deliver consistent gains across diverse workloads. As environments scale further, the techniques described here provide a foundation for maintaining efficiency while accommodating new storage and networking technologies.